|
Hi, my name is Dong Won. My advisors and friends usually call me “Don" :) I’m a final-year PhD Student at MIT, where I develop multimodal foundation models for human-robot social interaction to build real-world/real-time robotic systems for speech, perception, expression powering robots like Jibo, Sprout, Reachy Mini, and Astro. I am grateful to be advised by Prof. Cynthia Breazeal, Dr. Hae Won Park, and Prof. Louis-Philippe Morency. Prior to MIT, I graduated from CMU with M.S./B.S. in Machine Learning. My research is generously supported by the Amazon AI Fellowship . I also serve as an E14 VC Fund Fellow at MIT. Email: dongwonl_at_mit_dot_edu |
|
|
06/2026: Successfully proposed my PhD thesis, Multimodal Foundation Models as Communicative Robot Action Models. 04/2026: Our paper, Social Human Robot Embodied Conversation (SHREC) Dataset: Benchmarking Foundational Models’ Social Reasoning , was accepted to RSS 2026. 09/2025: Honored to be named an Amazon AI Research Innovation Fellow , supporting my doctoral research on multimodal social intelligence and foundation models for embodied AI. 09/2025: Selected as a 2025–2027 E14 VC Fund Fellow at MIT , working with the E14 Fund on early-stage venture activities. 09/2025: Our paper, Aligning Dialogue Agents with Global Feedback via Large Language Model Multimodal Reward Decomposition , was accepted to EMNLP 2025 Findings. 06/2025: Completed the MIT Research Mentoring Certificate Program, focused on effective and inclusive research mentoring. 04/2025: Gave a Rising Stars Student Spotlight talk at the MIT Media Lab Members’ Event on Embodied AI Agents in Real-World Social Interactions. 09/2024: Our paper, Global Reward to Local Rewards: Multimodal-Guided Decomposition for Improving Dialogue Agents , was accepted to EMNLP 2024 as an oral presentation. 06/2024: Joined Microsoft Research NYC as a research intern working on Human-Oriented AI. 08/2023: Joined MIT MAS.630: Advanced Seminar: Affective Computing and Ethics as a graduate teaching assistant. 07/2023: Our paper, Lecture Presentations Multimodal Dataset: Towards Understanding Multimodality in Educational Videos , was accepted to ICCV 2023. 07/2023: Our paper, HIINT: Historical, Intra-and Inter-personal Dynamics Modeling with Cross-person Memory Transformer , was accepted to ICMI 2023. 04/2023: Our paper, Multipar-T: Multiparty-Transformer for Capturing Contingent Behaviors in Group Conversations , was accepted to IJCAI 2023 as an oral presentation. 03/2023: Our proposal for the 1st Workshop on Social and Affective Intelligence (SAI) was accepted at ACII 2023. 03/2022: Our paper, Low-resource Adaptation for Personalized Co-Speech Gesture Generation , was accepted to CVPR 2022. 05/2021: We organized the First Workshop on Crossmodal Social Animation at ICCV 2021. 09/2020: Our paper, No Gestures Left Behind: Learning Relationships between Spoken Language and Freeform Gestures , was accepted to EMNLP 2020 Findings. 07/2020: Our paper, Style Transfer for Co-Speech Gesture Animation: A Multi-Speaker Conditional Mixture Approach , was accepted to ECCV 2020. |
|
|
|
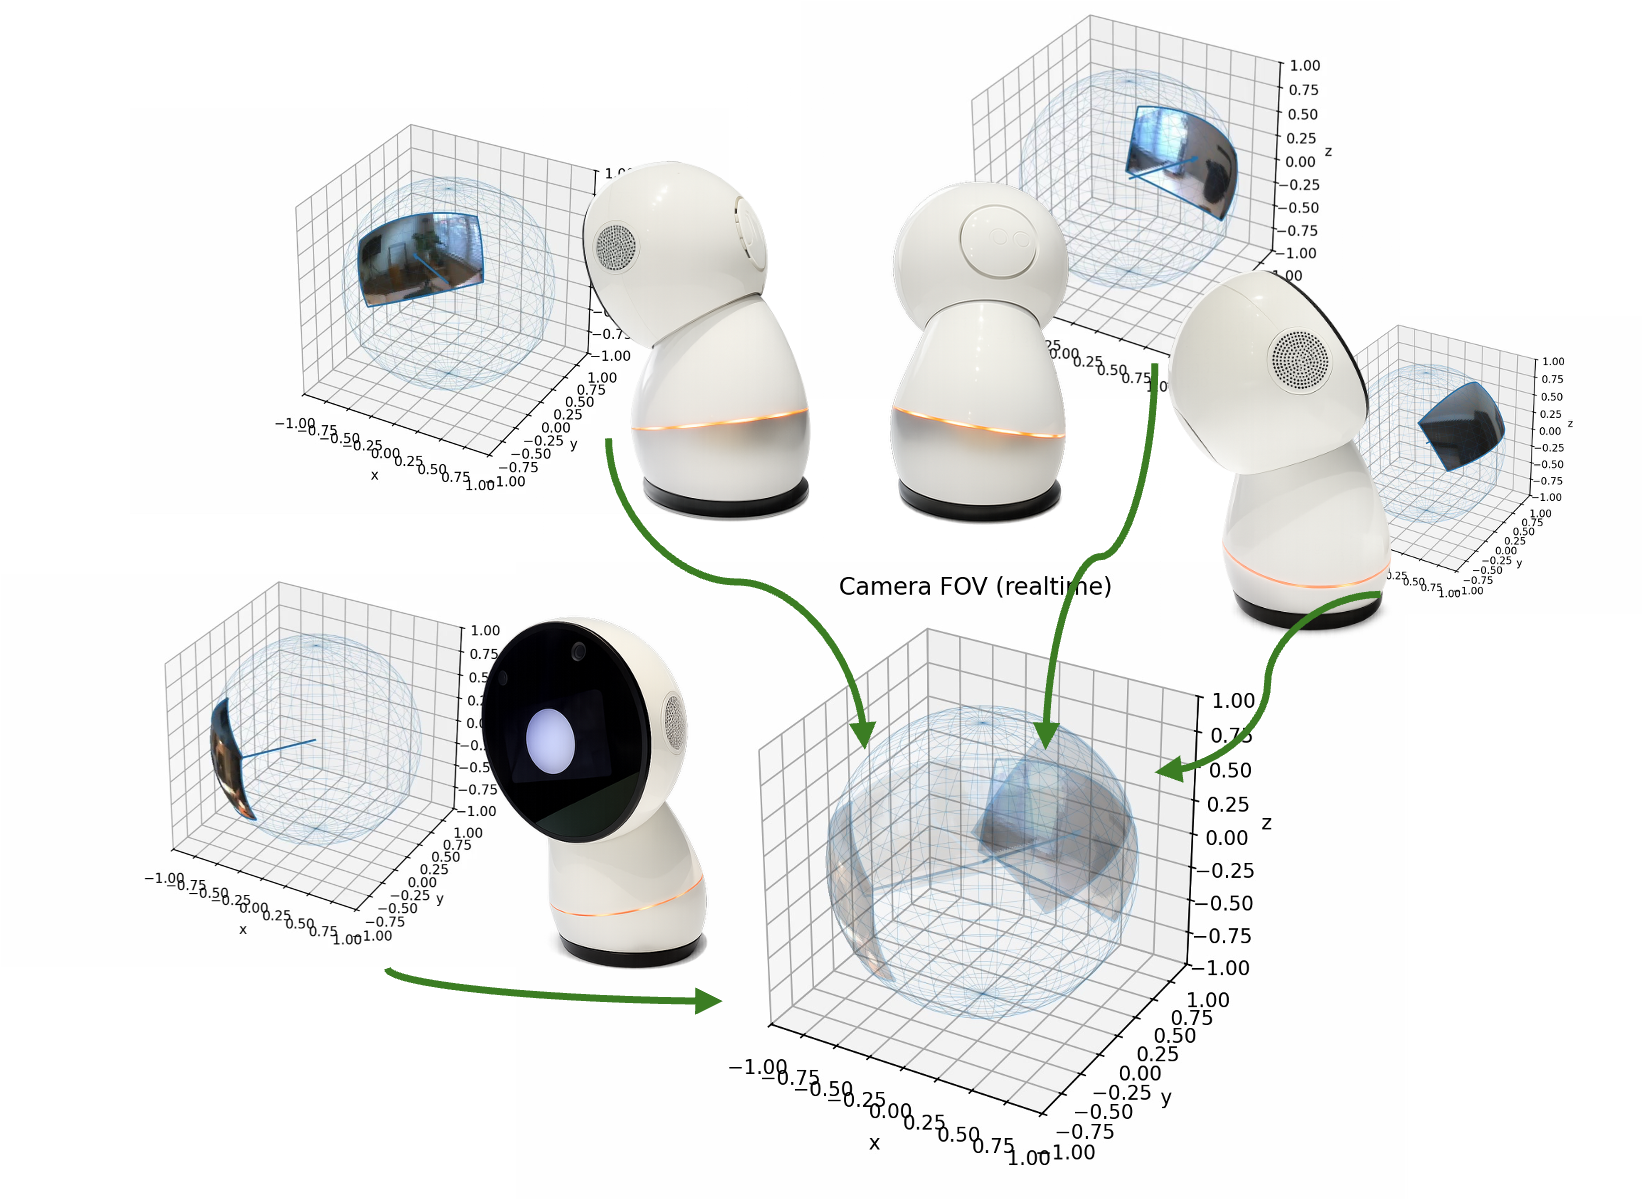
Dong Won Lee, Sarah Gillet, Louis-Philippe Morency, Cynthia Breazeal, Hae Won Park RSS Beyond the Lab Workshop, 2026 paper / website We present a minimal system recipe for situated embodied conversation that pairs a real-time multimodal language model with a small set of tools for attention and active perception, enabling robots to interleave dialogue with “what to look at, when to look, and what to say” under tight latency constraints. |
|
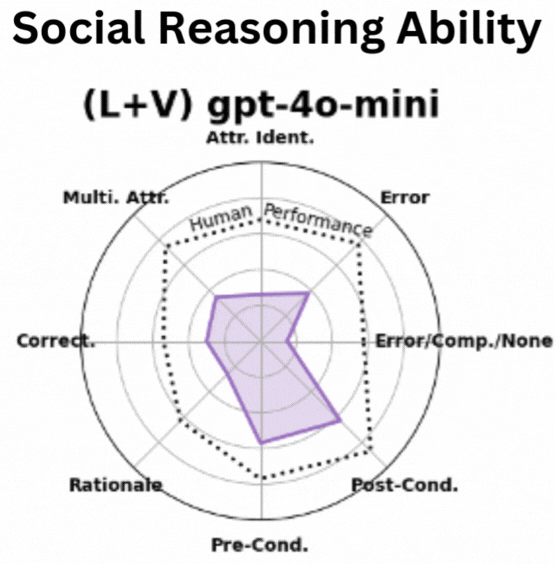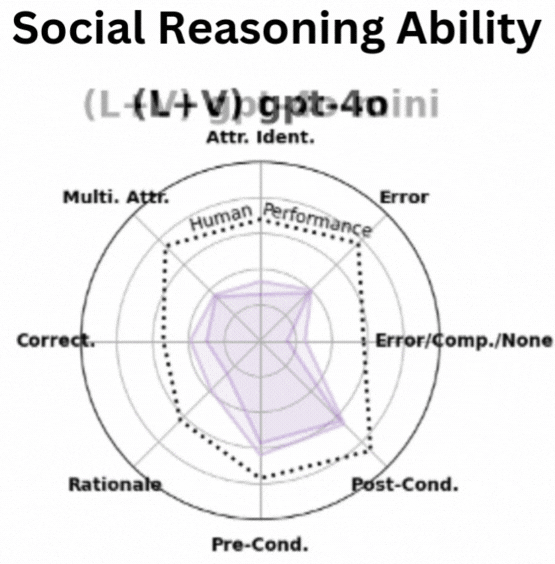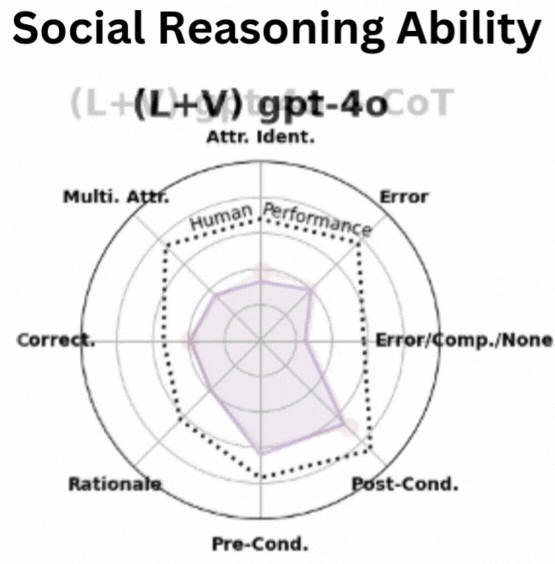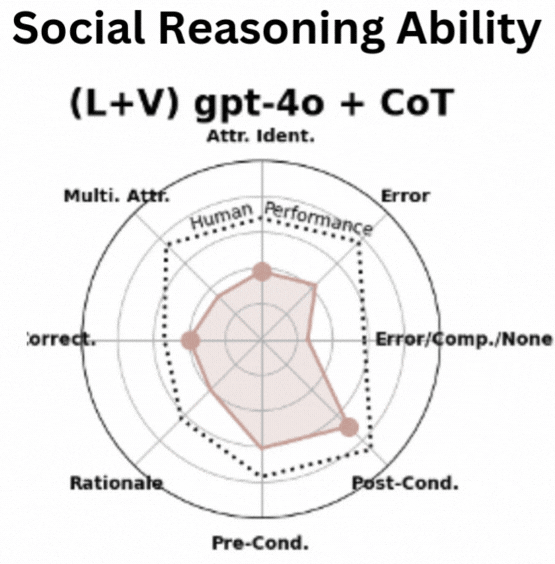
Dong Won Lee, Yubin Kim, Denison Guvenoz, Sooyeon Jeong, Parker Malachowsky, Louis-Philippe Morency, Cynthia Breazeal, Hae Won Park RSS, 2026 website / paper We introduce a large-scale collection of datasets of real-world human-robot interaction videos with 10K+ annotations to benchmark AI models' ability to identify and reason about social interactions, providing a foundation for advancing socially intelligent AI. |
|
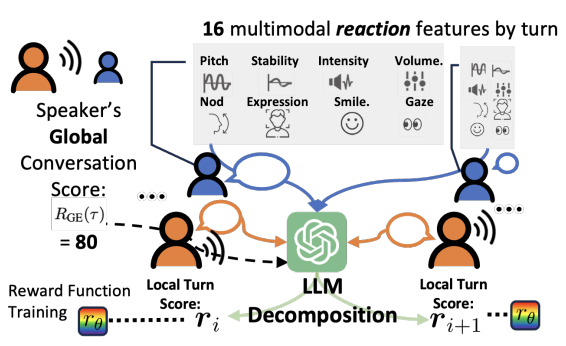
Dong Won Lee, Hae Won Park, Cynthia Breazeal, Louis-Philippe Morency EMNLP (Findings), 2025 paper We introduce a framework that uses a frozen large language model (LLM) to decompose global session-level feedback into fine-grained turn-level rewards for dialogue agents. Our method works in both text-only and multimodal settings using cues such as pitch and gaze, enabling reinforcement learning without dense supervision. The resulting reward models improve dialogue quality in human evaluations. |
|
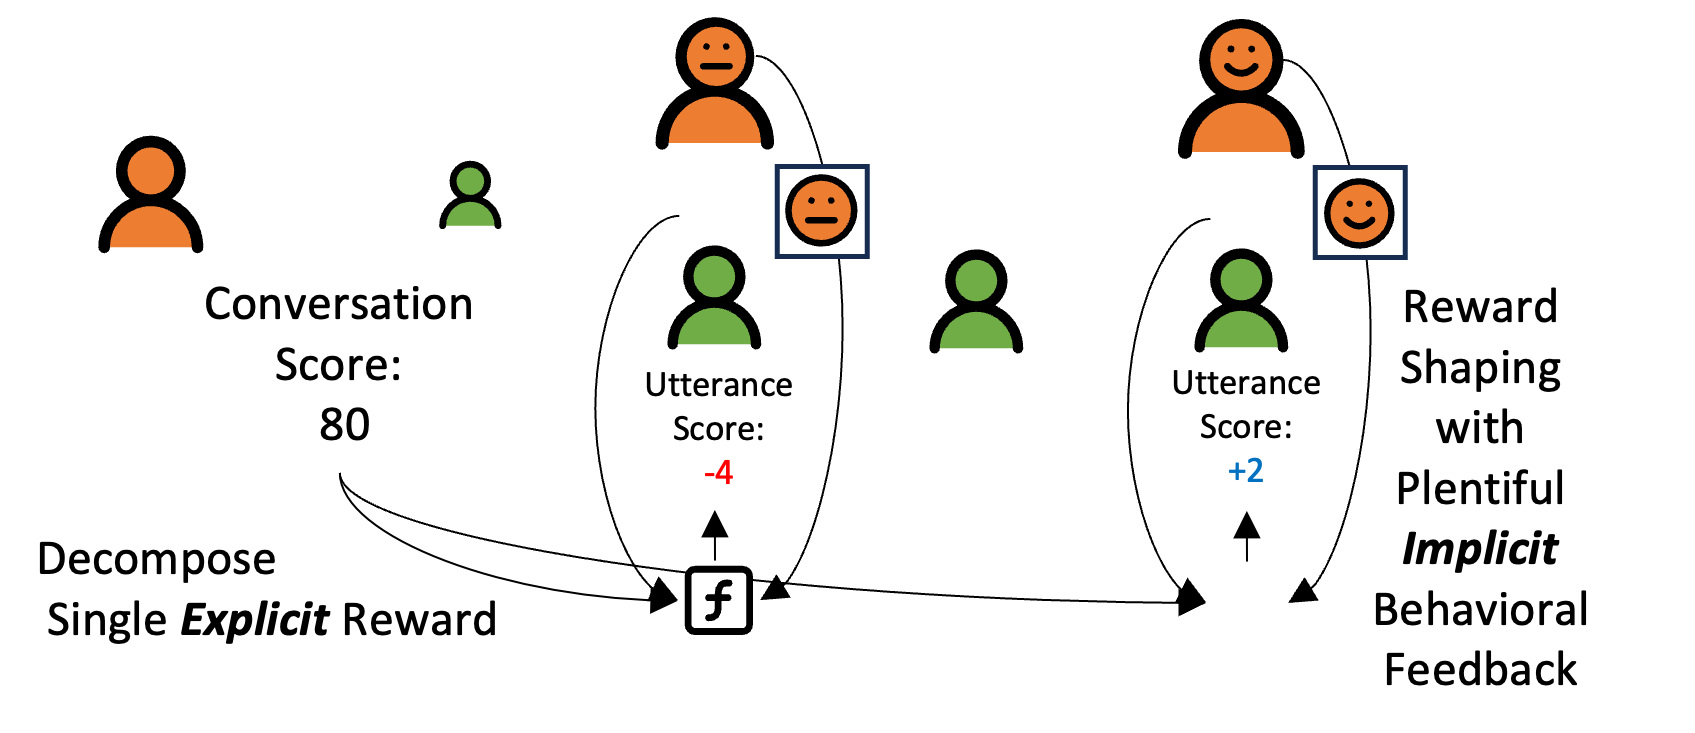
Dong Won Lee, Hae Won Park, Yoon Kim, Cynthia Breazeal, Louis-Philippe Morency EMNLP, 2024 (Oral) paper / code / huggingface We introduce an approach named GELI, which automatically decomposes a single Global Explicit post-interaction score while incorporating Local Implicit feedback from multimodal signals to adapt a language model to become more conversational. |
|
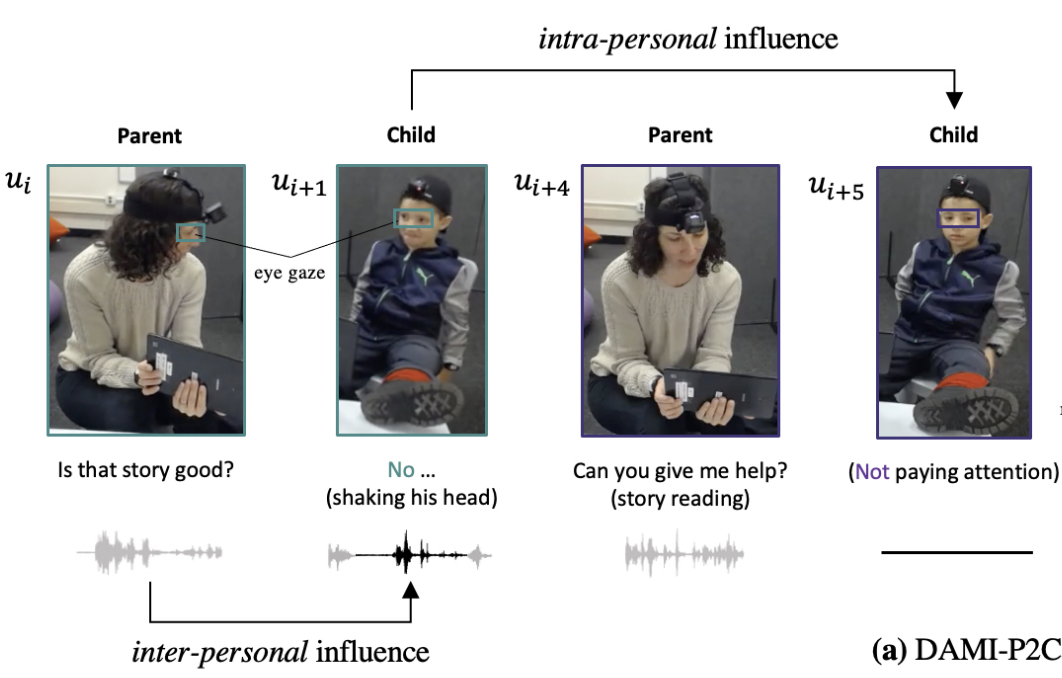
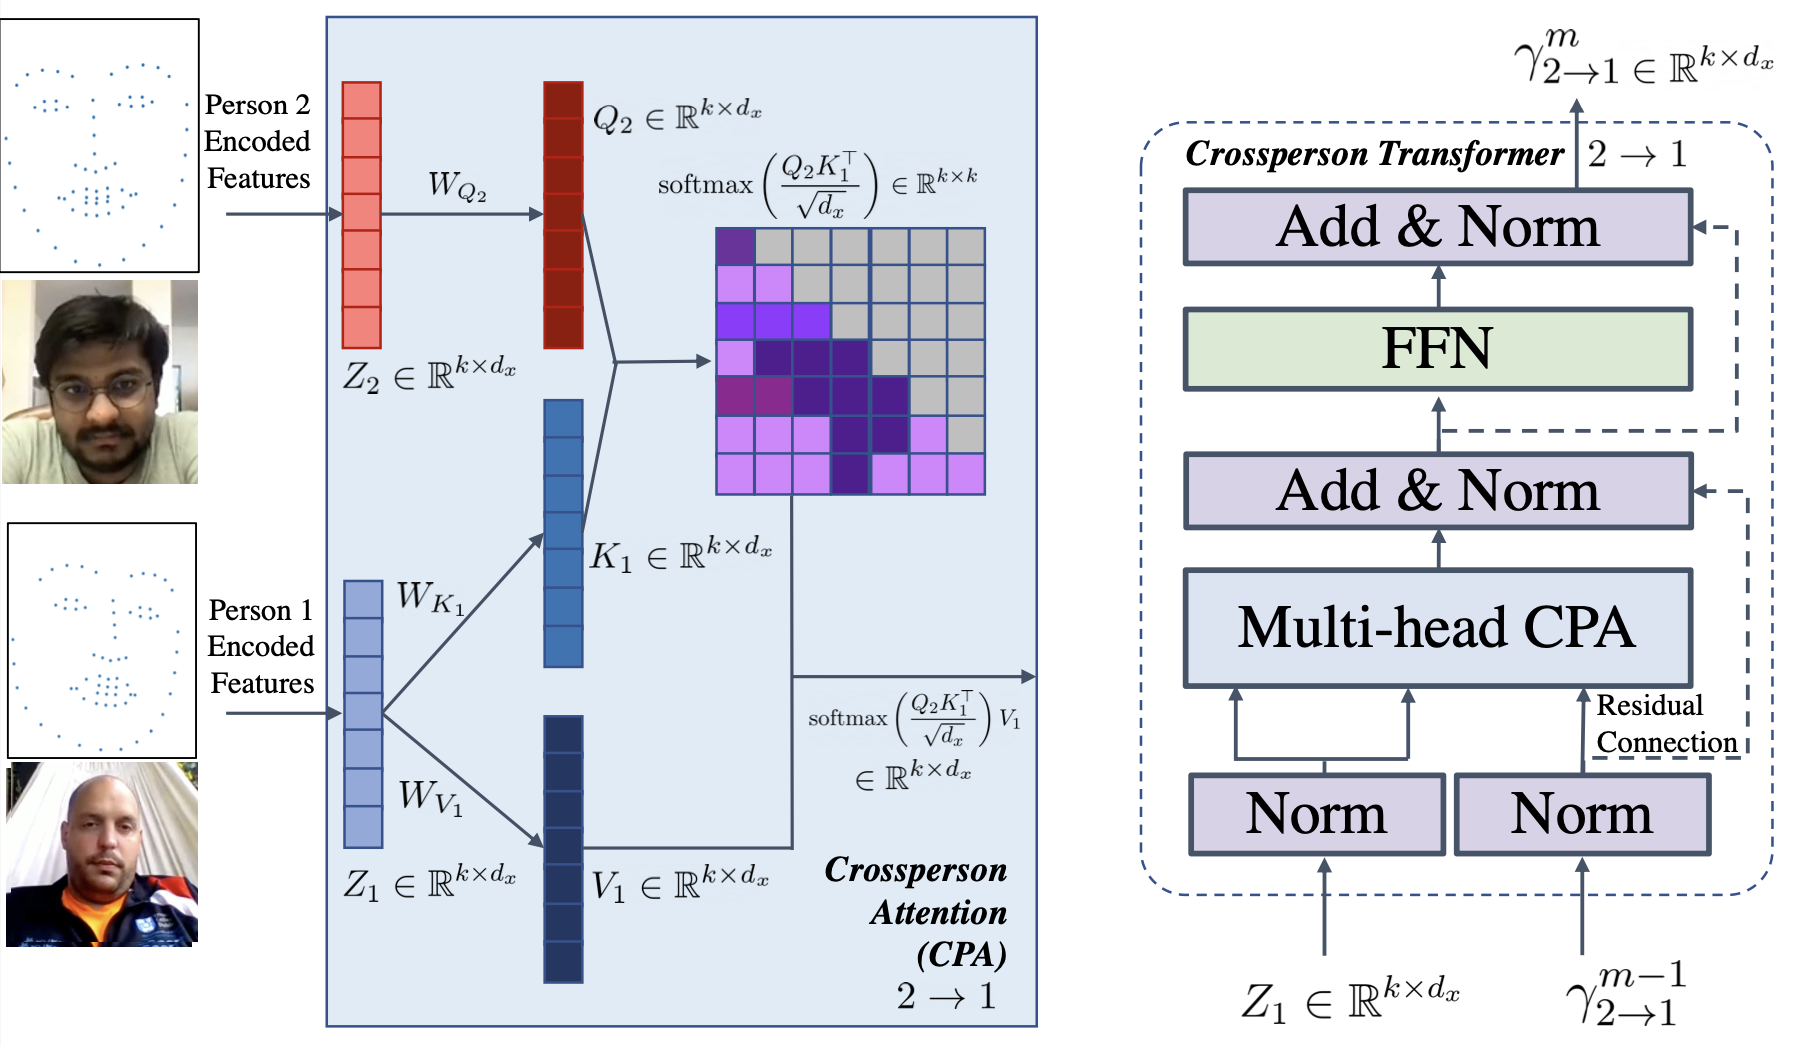
Yubin Kim, Dong Won Lee, Paul Pu Liang, Sharifa Algohwinem, Cynthia Breazeal, Hae Won Park ICMI, 2023 paper We model Historical, Intra-and Inter-personal (HIINT) Dynamics in conversation by incorporating memory modules in the Cross-person Memory Transformer to address temporal coherence and better represent the context of conversational behaviors. |
|
Dong Won Lee, Yubin Kim, Rosalind Picard, Cynthia Breazeal, Hae Won Park IJCAI, 2023 (Oral) paper We introduce a new transformer architecture to model contingent behaviors in multiparty group conversations. |
|
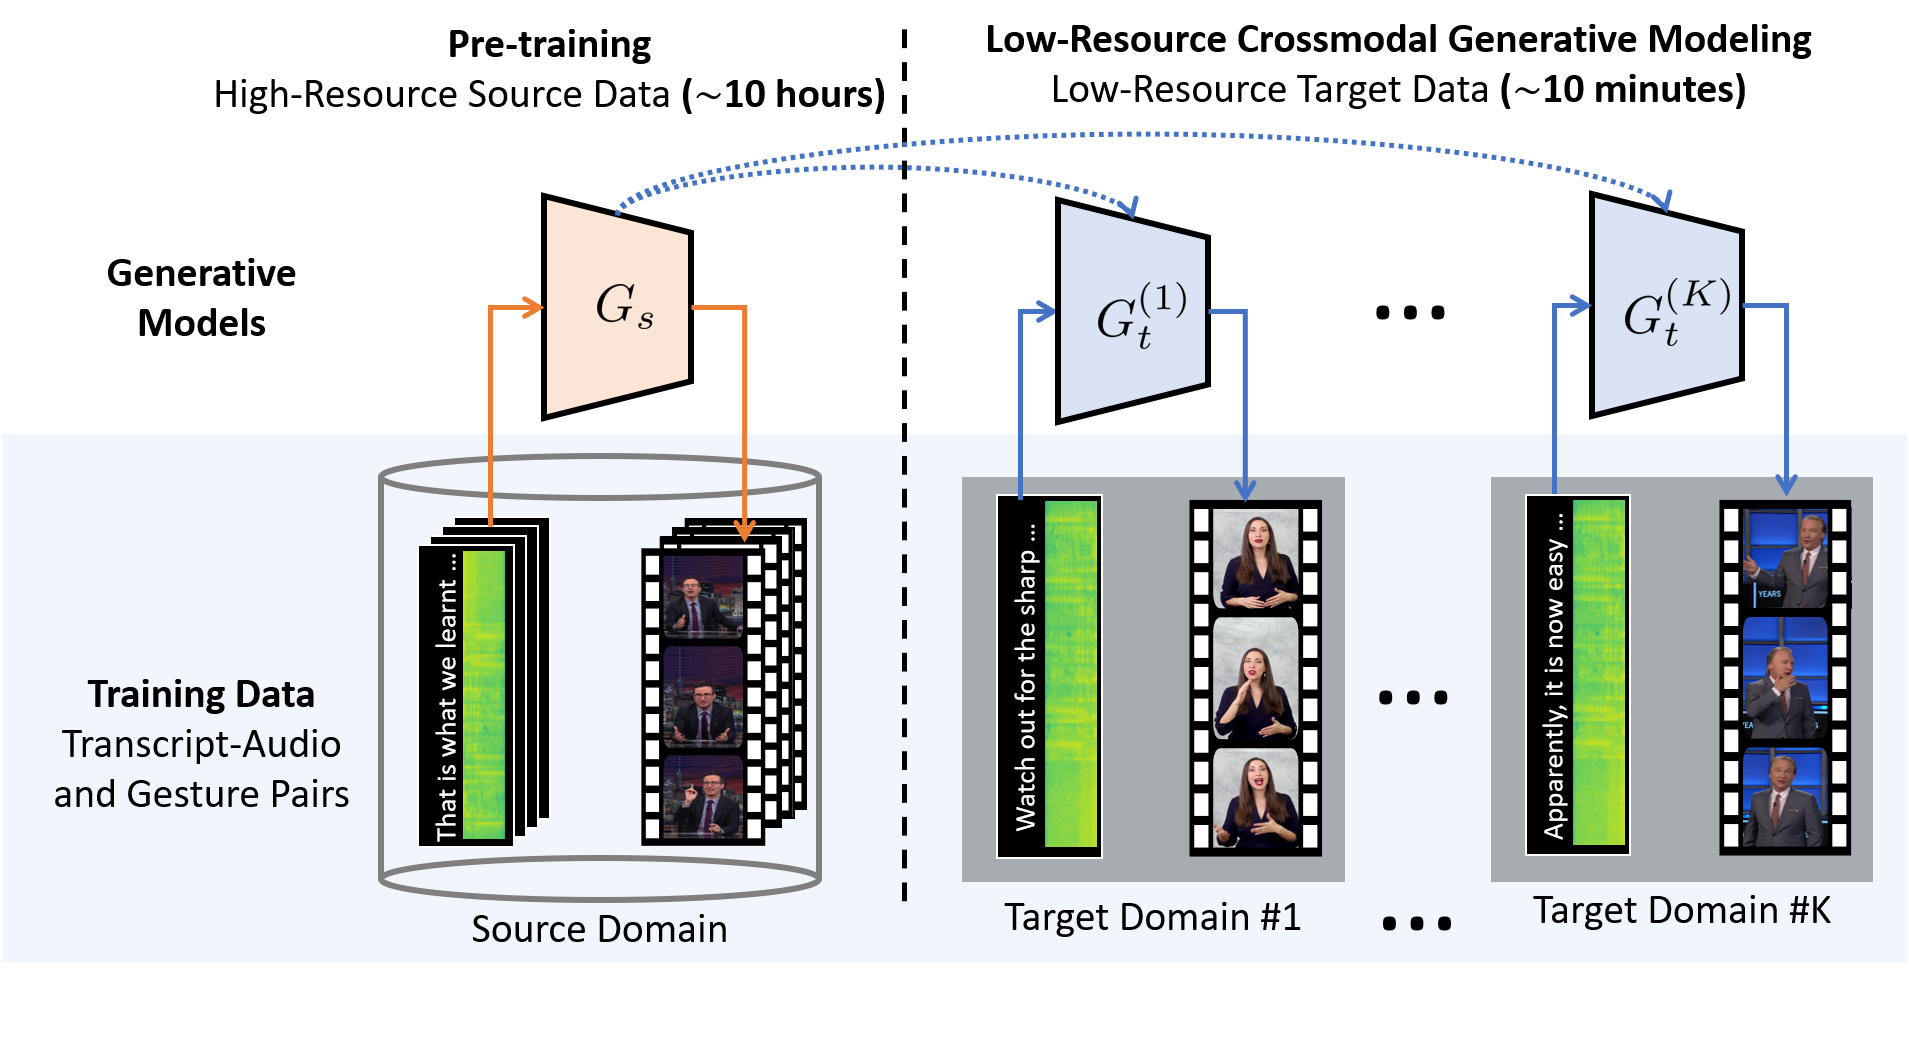
Chaitanya Ahuja, Dong Won Lee, Louis-Philippe Morency CVPR, 2022 paper We propose a new approach in crossmodal generative modeling in low-resource settings to create personalized gesture generation models with limited data from a new speaker. |
|
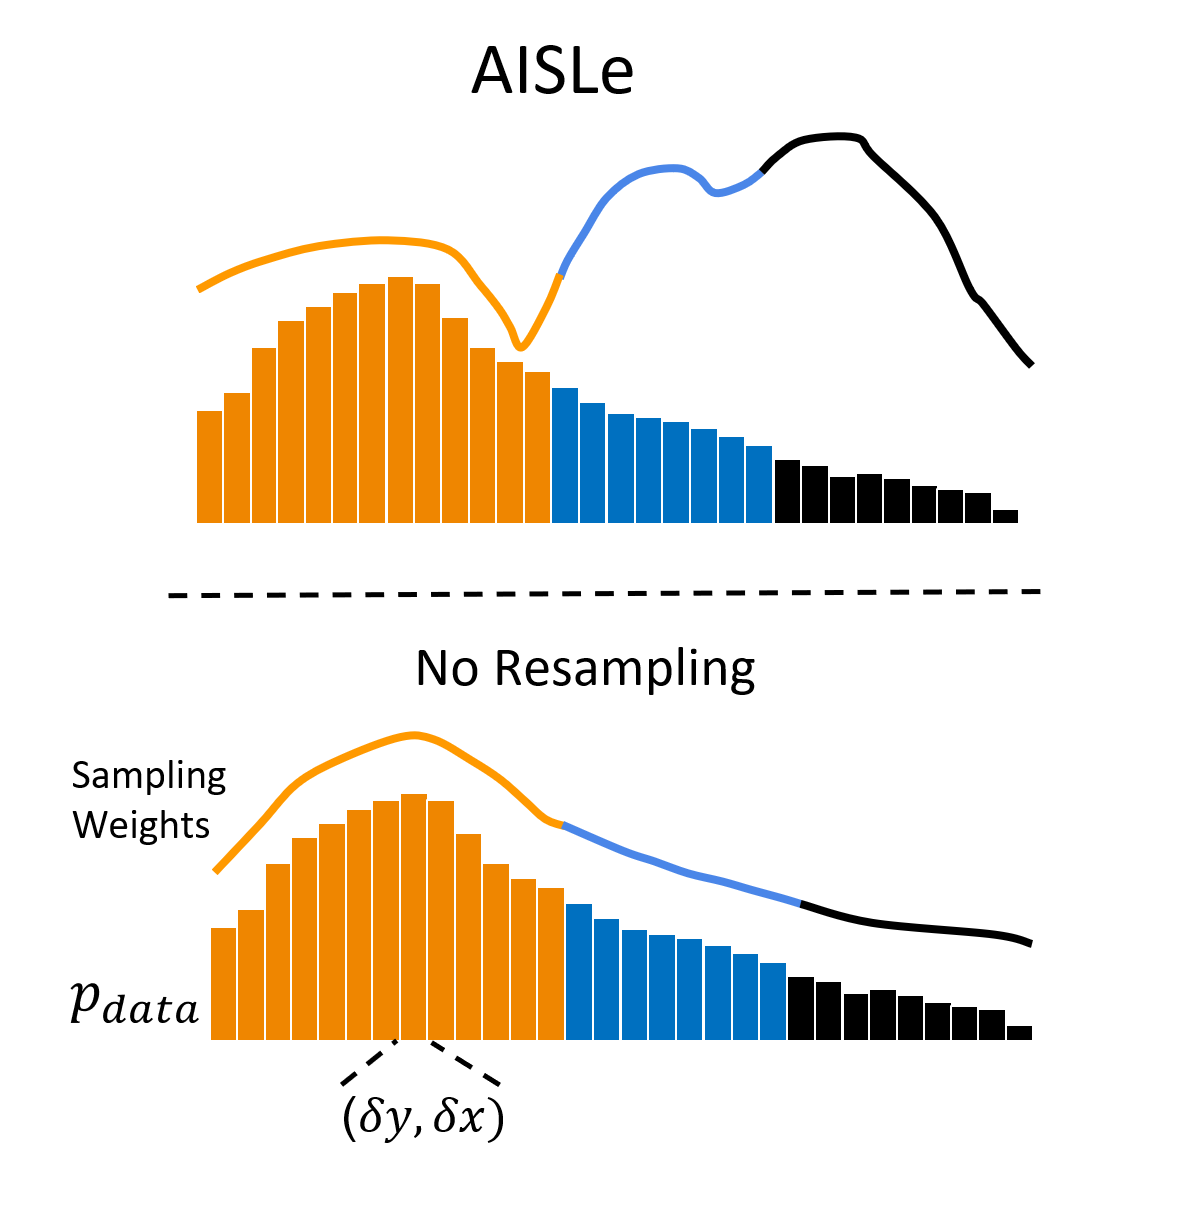
Chaitanya Ahuja, Dong Won Lee, Ryo Ishii, Louis-Philippe Morency EMNLP, Findings, 2020 paper / code We study relationships between spoken language and co-speech gestures to account for the long tail of the text-gesture distribution. |
|
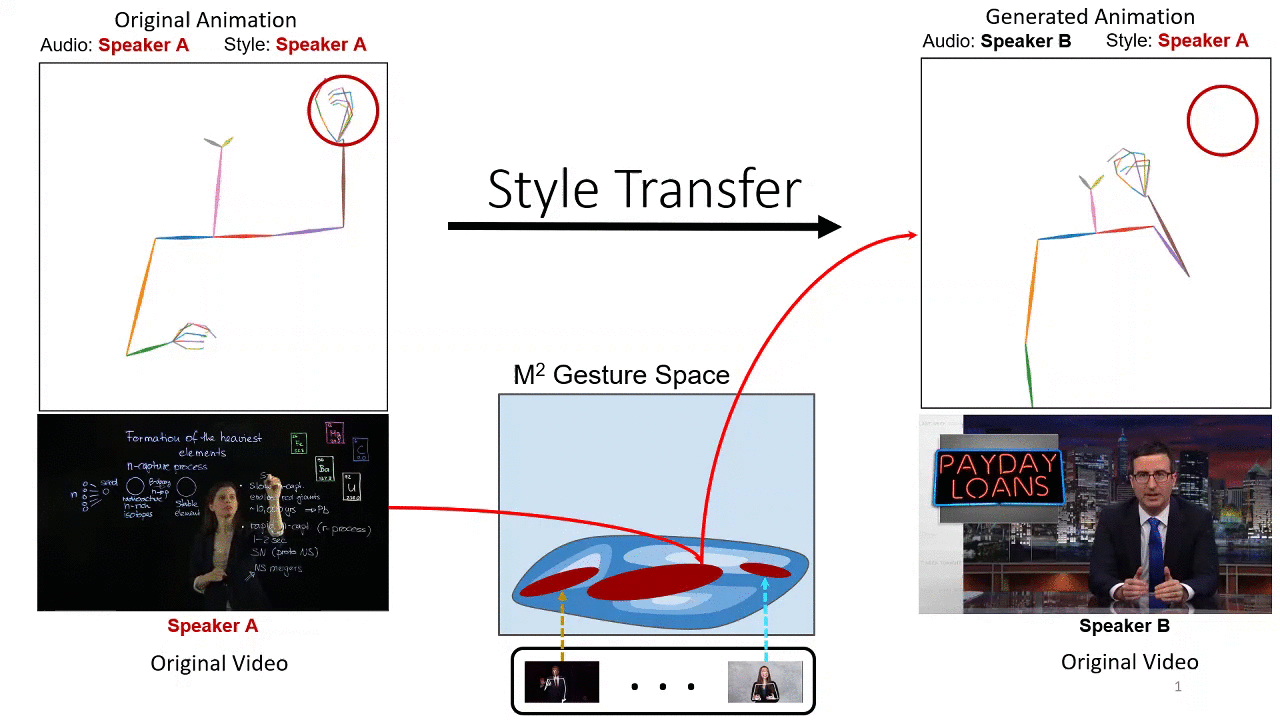
Chaitanya Ahuja, Dong Won Lee, Yukiko I. Nakano, Louis-Philippe Morency ECCV, 2020 project page / paper / code We propose a new style transfer model to learn individual styles of speakers' gestures. |
|
|
|
Graduate TA, Fall 2023 |
|
Graduate TA, Spring 2022 |
|
Graduate TA, Spring 2021 |
|
Undergraduate TA, Fall 2019, Spring 2020, Fall 2020 (3 Semesters) |
|
|
Undergraduate TA, Fall 2020, Spring 2021 (2 Semesters) |
|
|
|
Reviewer |
|
Co-Organizing Chair workshop page |
|
Publication Chair workshop page / video |
|
Reviewer |
|
Website Credits Here: source code |